|
Xin ZHANG Hi, there! I am a Ph.D. student majoring in Electrical and Computer Engineering(ECE) at National University of Singapore (NUS), supervised by Prof. Robby T. Tan. Before that, I received both my bachelor's and master's degrees from Beihang University, where I was advised by Prof. Yan Xu. My primary research interests center on multimodal large language models (MLLMs), particularly region-level understanding and grounding, alongside semantic segmentation, parameter-efficient fine-tuning, and vision foundation models. Email: x.zhang@u.nus.edu |

|
News
|
[Oct. 2026] Three papers accepted to NeurIPS 2026! [Jul. 2026] Our paper "Actor as Its Own Critic: Unifying Region Understanding and Localization via CycleGRPO" is accepted to ECCV 2026! [Apr. 2025] Our paper "Mamba as a Bridge: Where Vision Foundation Models Meet Vision Language Models for Domain-Generalized Semantic Segmentation" is selected as a CVPR 2025 Highlight! |
Publications
|
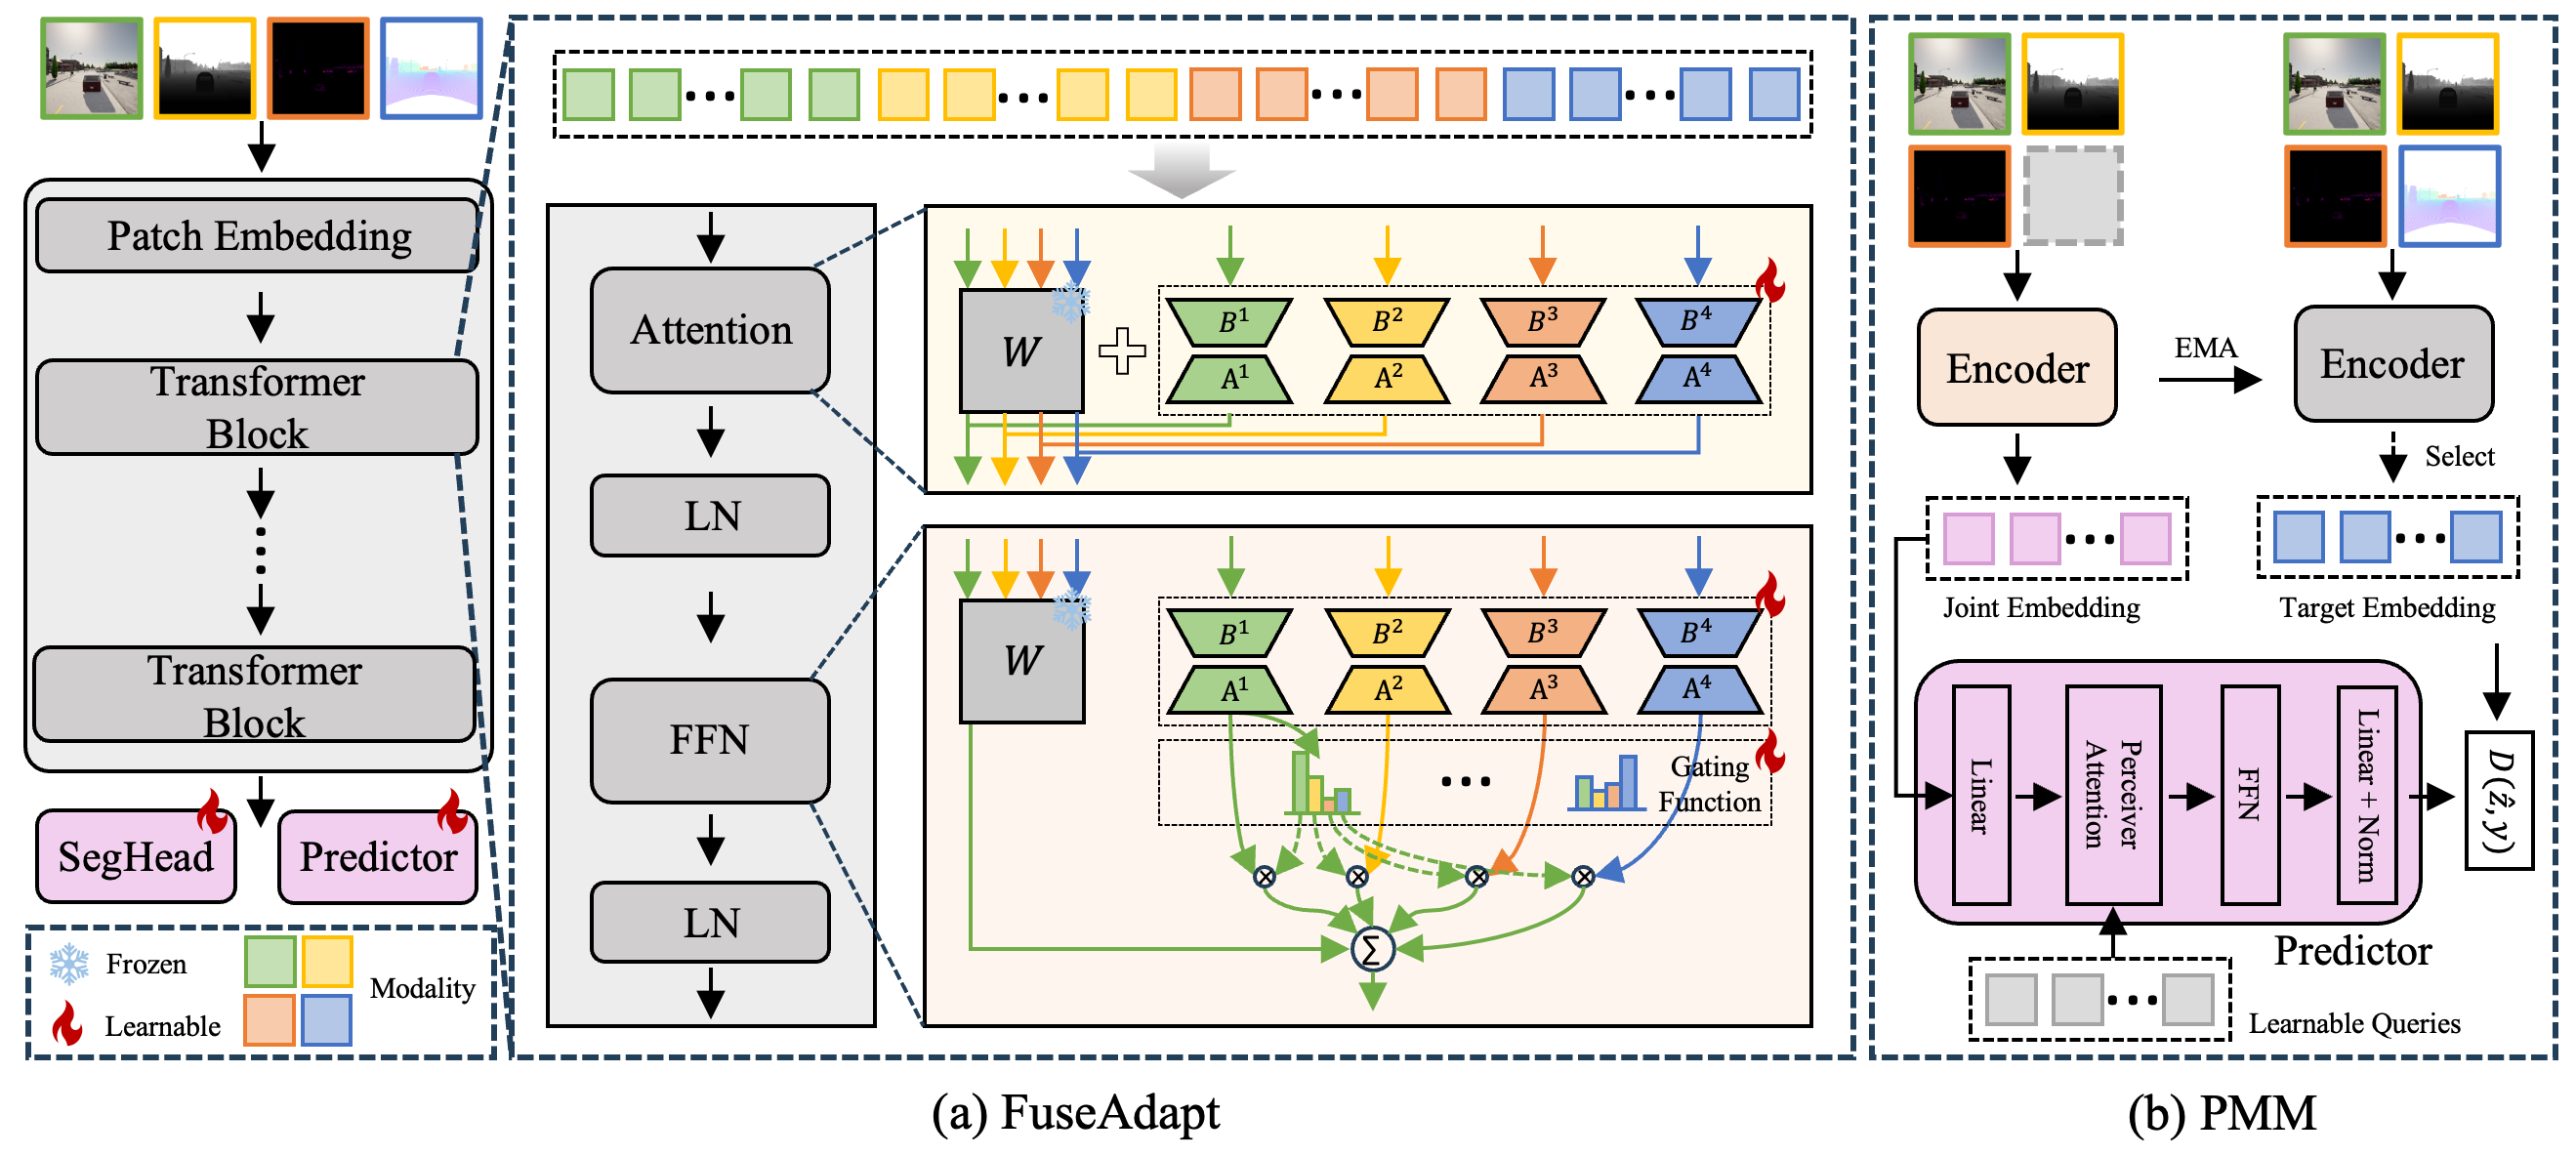
FuseAdapt: Parameter-Efficient Multimodal Fusion for Semantic Segmentation with Missing Modalities Xin Zhang, Robby T. Tan Advances in Neural Information Processing Systems (NeurIPS), 2026 We propose FuseAdapt, a parameter-efficient framework that combines modality-private adaptation, cross-modal residual fusion, and predictive modality modeling for semantic segmentation with missing modalities. |

|
Actor as Its Own Critic: Unifying Region Understanding and Localization via CycleGRPO
Xin Zhang*, Haochen Wang*, Yikang Zhou, Zhuochen Wang, Xiangtai Li, Robby T. Tan European Conference on Computer Vision (ECCV), 2026 Project Page / Paper / Code / Model We introduce CycleGRPO, a self-evaluating reinforcement learning framework that closes the region-to-text-to-region loop, jointly improving region understanding and localization without caption ground truth. |

|
Mamba as a Bridge: Where Vision Foundation Models Meet Vision Language Models for Domain-Generalized Semantic Segmentation
Xin Zhang, Robby T. Tan The IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025 (Highlight) We propose MFuser, a lightweight Mamba-based framework that efficiently fuses vision foundation and vision-language models, achieving state-of-the-art performance in domain-generalized semantic segmentation with strong spatial and semantic alignment. |

|
ERF: A Benchmark Dataset for Robust Semantic Segmentation Under Extreme Rainfall Conditions
Xin Yang, Xin Zhang, Xinchao Wang The Association for the Advancement of Artificial Intelligence (AAAI), 2025 (Oral) We introduce ERF, the first benchmark for semantic segmentation under violent rain, revealing major model robustness gaps. |

|
HEAP: Unsupervised Object Discovery and Localization with Contrastive Grouping
Xin Zhang, Jinheng Xie, Yuan Yuan, Michael Bi Mi, Robby T. Tan The Association for the Advancement of Artificial Intelligence (AAAI), 2024 We propose a hierarchical contrastive grouping framework, HEAP, for unsupervised object discovery and localization. |

|
Adaptive Domain Generalization via Online Disagreement Minimization
Xin Zhang, Ying-Cong Chen IEEE Transactions on Image Processing (TIP), 2023 This work introduces AdaODM, which adapts models at test time by reducing classifier disagreement, boosting generalization to unseen domains. |
|
Gigapixel Whole-Slide Images Classification Using Locally Supervised Learning
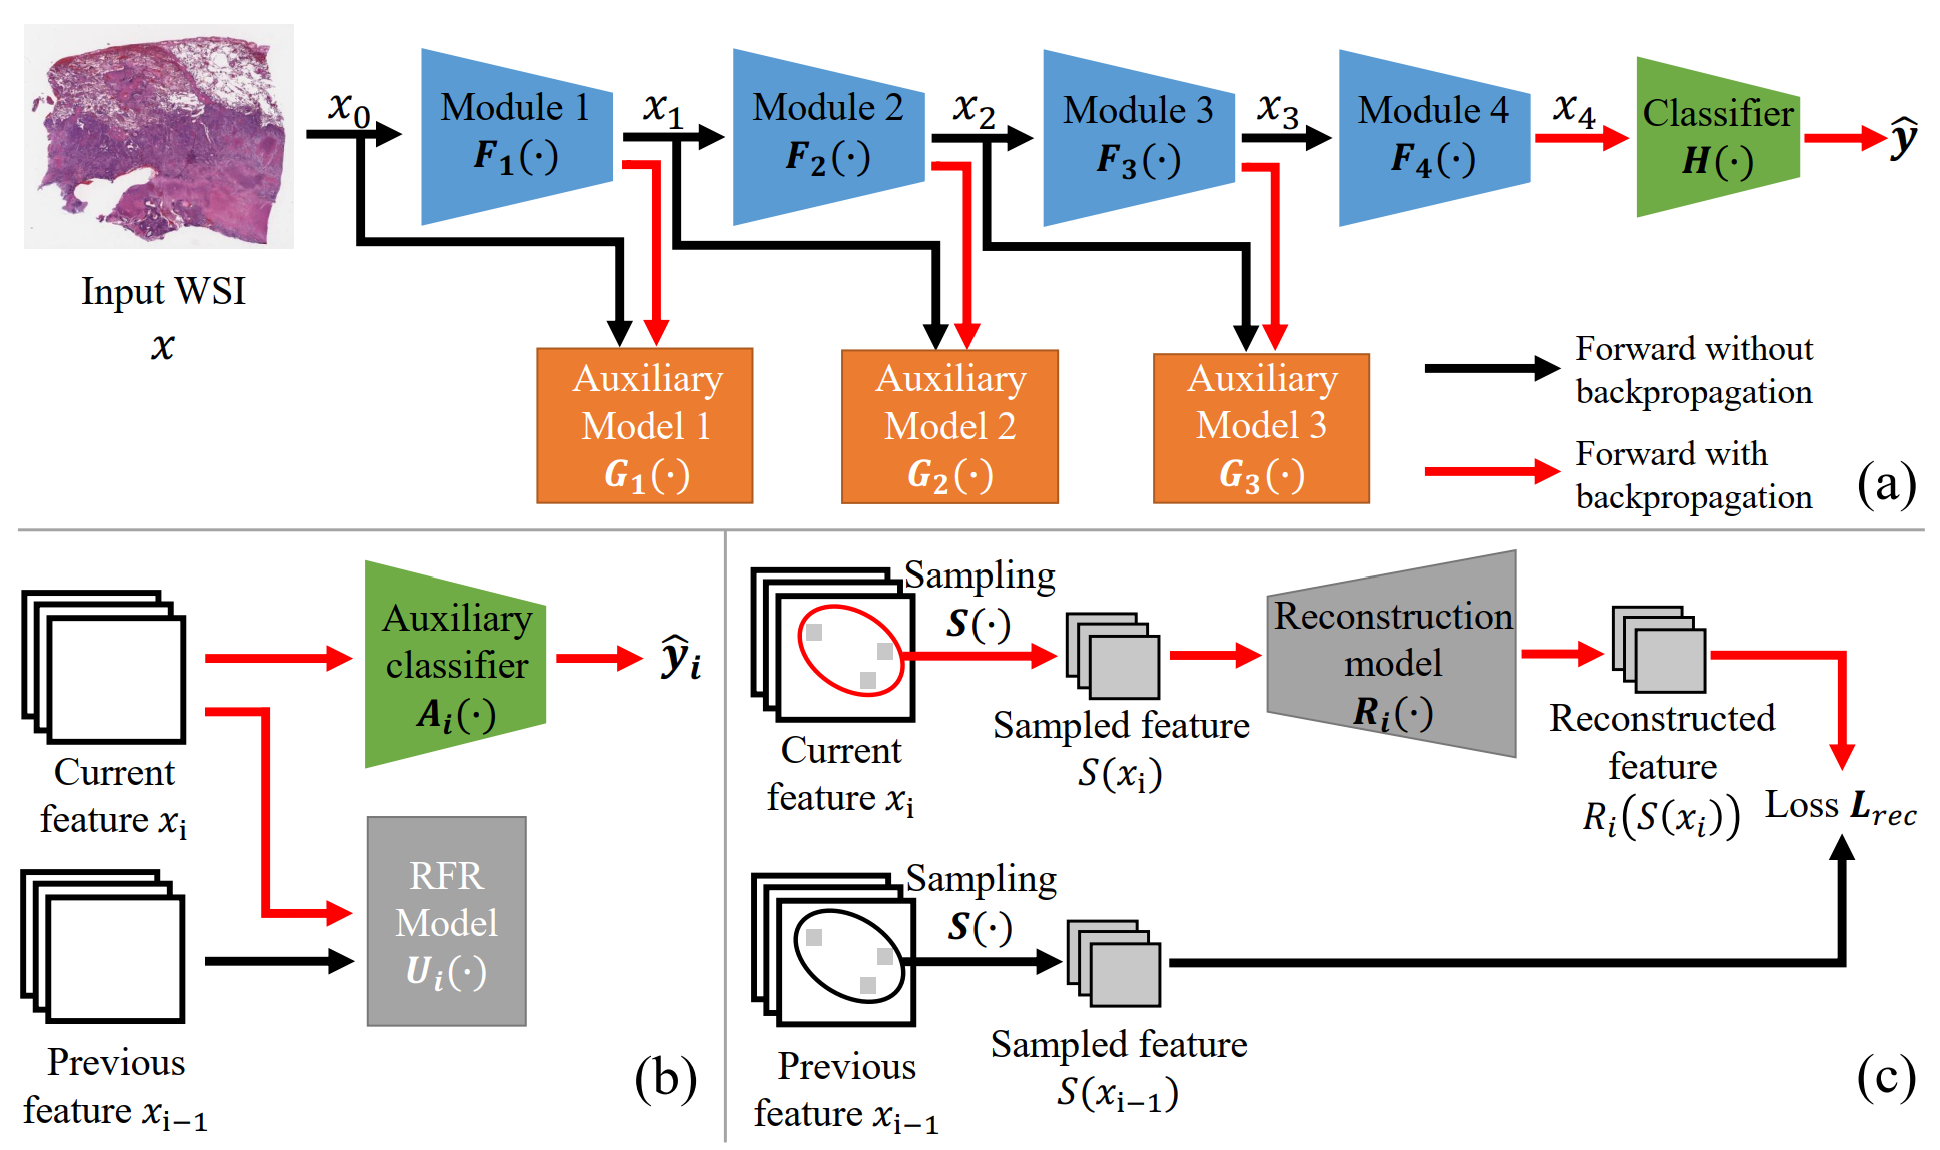
Jingwei Zhang*, Xin Zhang*, Ke Ma, Rajarsi Gupta, Joel Saltz, Maria Vakalopoulou, Dimitris Samaras International Conference on Medical Image Computing and Computer-Assisted Intervention (MICCAI), 2022 (Oral) Paper / Code We propose a locally supervised learning framework for gigapixel whole-slide image classification, capturing local and global information while reducing computation and GPU memory requirements. |
Academic Services
|
Serve as a reviewer for CVPR, ICCV, ECCV, NeurIPS, ICML, ICLR, AAAI, MICCAI, TPAMI, TMLR. |
Awards
|
[2020] Outstanding Master’s Graduate of Beijing [2019] National Scholarship |
|
|